


All we know an attractive certification will help you to find a decent job and get a promotion, such as Associate-Developer-Apache-Spark-3.5. Associate-Developer-Apache-Spark-3.5 test dump is a kind of certification that you can improve yourself and help you to stand out from other people. If you pass Associate-Developer-Apache-Spark-3.5 test dump you will have a good reputation and considerable salary and make friends with different successful men in the bright future. Databricks Certification certification can be used in different IT Company and it will be your access to the IT elites. But you may find that the Associate-Developer-Apache-Spark-3.5 test dump is difficult for you. You need much time to prepare and the cost of the Associate-Developer-Apache-Spark-3.5 test dump is high, you wonder it will be a great loss for you when fail the exam. It will be bad thing. Our TestsDumps will help you to reduce the loss and save the money and time for you.

TestsDumps is a one of the Databricks exam questions providers of Associate-Developer-Apache-Spark-3.5 test dump in the IT industry that ensure you to pass the Associate-Developer-Apache-Spark-3.5 test almostly 100%. We have experienced and professional IT experts to create the latest Associate-Developer-Apache-Spark-3.5 test dump and Databricks Associate-Developer-Apache-Spark-3.5 study guide dump which is approach to the real exam questions. We will provide you the accurate Associate-Developer-Apache-Spark-3.5 test dump questions and Associate-Developer-Apache-Spark-3.5 practice dump which attach the correct answers and detailed explanation and analysis. You just need to take 20-30 hours to learn the Associate-Developer-Apache-Spark-3.5 test Databricks Certified Associate Developer for Apache Spark 3.5 - Python dump questions and know it skillfully; you will pass the exam easily. If you get any problems and doubts about Associate-Developer-Apache-Spark-3.5 test dump questions you can contact our customer service freely and they will solve the problems.
You can download the free demo of Associate-Developer-Apache-Spark-3.5 test dumps questions before you buy, and you have the right to one-year free update the Associate-Developer-Apache-Spark-3.5 test dump questions after you pay. And there are three versions for you choose. The PDF version of Associate-Developer-Apache-Spark-3.5 test dump questions means that you can print it out and practice it on the paper, it is very convenient for people who are not available to the computer. For software version, the most advantage is that you can stimulate the real Associate-Developer-Apache-Spark-3.5 test dumps scene, you can practice the Associate-Developer-Apache-Spark-3.5 test dump like the real test and limit your test time so that you can know your shortcoming and improve your ability. But you can only use the software version on the computer. The third version is On-line APP, the function of On-line Associate-Developer-Apache-Spark-3.5 (Databricks Certified Associate Developer for Apache Spark 3.5 - Python) test dump is same as the software version, the difference between the two versions is that On-line APP can use be all electronic products, such as: iPad, iWatch but the Associate-Developer-Apache-Spark-3.5 test dump of software version is only used in the computer. So you can choose your best version according to your studying habits.
Our website offers 24/7 customer service assisting to you, in case you may get some problems in the course of learning Associate-Developer-Apache-Spark-3.5 test dump. And we adheres the principle of No help, Full refund, and you can get your money back when you fail the Associate-Developer-Apache-Spark-3.5 test dump.
After purchase, Instant Download: Upon successful payment, Our systems will automatically send the product you have purchased to your mailbox by email. (If not received within 12 hours, please contact us. Note: don't forget to check your spam.)
Databricks Associate-Developer-Apache-Spark-3.5 Exam Syllabus Topics:
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Using Spark SQL | 20% | - Working with functions and expressions - Using catalog and metadata APIs - Integrating Spark SQL with DataFrames - Running SQL queries |
| Topic 2: Using Spark Connect to Deploy Applications | 5% | - Spark Connect architecture - Connecting to remote Spark clusters - Running applications via Spark Connect |
| Topic 3: Troubleshooting and Tuning Apache Spark DataFrame API Applications | 10% | - Debugging and logging - Identifying performance bottlenecks - Managing memory and resource usage - Optimizing transformations and actions |
| Topic 4: Structured Streaming | 10% | - Fault tolerance and state management - Defining streaming queries - Streaming concepts and architecture - Output modes and triggers |
| Topic 5: Developing Apache Spark DataFrame API Applications | 30% | - Handling missing values and data quality - Selecting, renaming, and modifying columns - Reading and writing data in various formats - Filtering, sorting, and aggregating data - Partitioning and bucketing data - Joining and combining datasets - Creating DataFrames and defining schemas - User-defined functions (UDFs) |
| Topic 6: Using Pandas API on Apache Spark | 5% | - Key differences and limitations - Overview of Pandas API on Spark - Converting between Pandas and Spark structures |
| Topic 7: Apache Spark Architecture and Components | 20% | - Execution hierarchy and lazy evaluation - Execution and deployment modes - Fault tolerance and garbage collection - Spark architecture overview - Shuffling, actions, and broadcasting |
Databricks Certified Associate Developer for Apache Spark 3.5 - Python Sample Questions:
A developer notices that all the post-shuffle partitions in a dataset are smaller than the value set for spark.sql.adaptive.maxShuffledHashJoinLocalMapThreshold.
Which type of join will Adaptive Query Execution (AQE) choose in this case?
- A. A Cartesian join
- B. A broadcast nested loop join
- C. A shuffled hash join
- D. A sort-merge join
Correct Answer: C 🗳️
Explanation: Only visible for TestsDumps members. You can sign-up / login (it's free).
39 of 55.
A Spark developer is developing a Spark application to monitor task performance across a cluster.
One requirement is to track the maximum processing time for tasks on each worker node and consolidate this information on the driver for further analysis.
Which technique should the developer use?
- A. Broadcast a variable to share the maximum time among workers.
- B. Use an accumulator to record the maximum time on the driver.
- C. Use an RDD action like reduce() to compute the maximum time.
- D. Configure the Spark UI to automatically collect maximum times.
Correct Answer: C 🗳️
Explanation: Only visible for TestsDumps members. You can sign-up / login (it's free).
An MLOps engineer is building a Pandas UDF that applies a language model that translates English strings into Spanish. The initial code is loading the model on every call to the UDF, which is hurting the performance of the data pipeline.
The initial code is: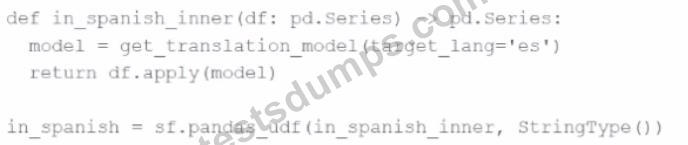
def in_spanish_inner(df: pd.Series) -> pd.Series:
model = get_translation_model(target_lang='es')
return df.apply(model)
in_spanish = sf.pandas_udf(in_spanish_inner, StringType())
How can the MLOps engineer change this code to reduce how many times the language model is loaded?
- A. Convert the Pandas UDF from a Series → Series UDF to an Iterator[Series] → Iterator[Series] UDF
- B. Convert the Pandas UDF from a Series → Series UDF to a Series → Scalar UDF
- C. Convert the Pandas UDF to a PySpark UDF
- D. Run the in_spanish_inner() function in a mapInPandas() function call
Correct Answer: A 🗳️
Explanation: Only visible for TestsDumps members. You can sign-up / login (it's free).
A data engineer wants to process a streaming DataFrame that receives sensor readings every second with columns sensor_id, temperature, and timestamp. The engineer needs to calculate the average temperature for each sensor over the last 5 minutes while the data is streaming.
Which code implementation achieves the requirement?
Options from the images provided:
- A.

- B.
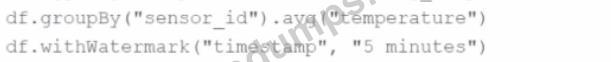
- C.

- D.

Correct Answer: C 🗳️
Explanation: Only visible for TestsDumps members. You can sign-up / login (it's free).
13 of 55.
A developer needs to produce a Python dictionary using data stored in a small Parquet table, which looks like this:
region_id
region_name
10
North
12
East
14
West
The resulting Python dictionary must contain a mapping of region_id to region_name, containing the smallest 3 region_id values.
Which code fragment meets the requirements?
- A. regions_dict = regions.select("region_id", "region_name").take(3)
- B. regions_dict = dict(regions.take(3))
- C. regions_dict = dict(regions.select("region_id", "region_name").rdd.collect())
- D. regions_dict = dict(regions.orderBy("region_id").limit(3).rdd.map(lambda x: (x.region_id, x.region_name)).collect())
Correct Answer: D 🗳️
Explanation: Only visible for TestsDumps members. You can sign-up / login (it's free).


 Hobart

 Amos

 Olive
 Merlin
 Winfred

 Nicole
 Alexander
 Helen
 Hale
 Marcus
 Bruce
 Setlla
 Michell


