

Latest [Jun 04, 2026] Snowflake DAA-C01 Exam Practice Test To Gain Brilliante Result
Take a Leap Forward in Your Career by Earning Snowflake DAA-C01
NEW QUESTION # 39
A retail company wants to understand the relationship between promotional campaigns and sales uplift across different store locations and product categories. You have the following Snowflake tables: 'SALES': 'transaction id', 'store id', 'product_category', 'sale date', 'sale_amount' 'PROMOTIONS': 'promotion id', 'store id', 'product category', 'promotion start date', promotion_end_date', 'discount_percentage' Which analytical approach and corresponding SQL query would be MOST effective in determining if specific promotional campaigns consistently result in a statistically significant sales uplift, considering potential variations across different store locations and product categories? Assume you want to compare sales during the promotion period to a control period (before the promotion). (Select TWO)
- A. Run a series of AIB tests by randomly assigning different discount percentages to different stores and product categories during the promotion period and track the resulting sales uplift, using a Mann-Whitney U test for statistical significance.
- B. Create a complex query that joins SALES and PROMOTIONS and calculates the percentage increase in sales during the promotion period compared to the average sales for the same store and product category in the 3 months prior, ignoring the potential for seasonality and other confounding factors.
- C. Employ a difference-in-differences (DID) approach, comparing the change in sales from the control period to the promotion period for the 'treatment group' (stores/product categories with promotions) relative to the change for a 'control group' (stores/product categories without promotions). This requires careful identification of suitable control groups.
- D. Calculate the average sales amount for each store and product category during promotion periods and compare it to the overall average sales amount across all periods using a t-test or similar statistical test to determine significance. This would involve exporting data into a statistical tool.
- E. Use a simple linear regression model in a Snowflake UDF (User-Defined Function) to predict sales based on the presence or absence of a promotion, without accounting for store or product category fixed effects.
Answer: C,D
Explanation:
Options A and C are the most effective. Option A utilizes t-tests to assess the statistical significance of sales during promotion periods versus the overall average. Combining statistical analysis with Snowflake data extraction provides insightful results. Option C proposes the Difference-in-Differences (DID) approach which is very effective. It uses a control group to account for external factors that may have also influenced sales. Comparing treated (promotion stores) and controlled store to find the diff in diff provides statistically significant evidence. Options B and E are less rigorous. B doesn't account for important fixed effects and E doesn't consider seasonality and confounding factors. Option D suggests an AIB test which is not practical as sales can not be assigned randomly during a promotion.
NEW QUESTION # 40
The image shows a table with a variant column that is storing a JSON record: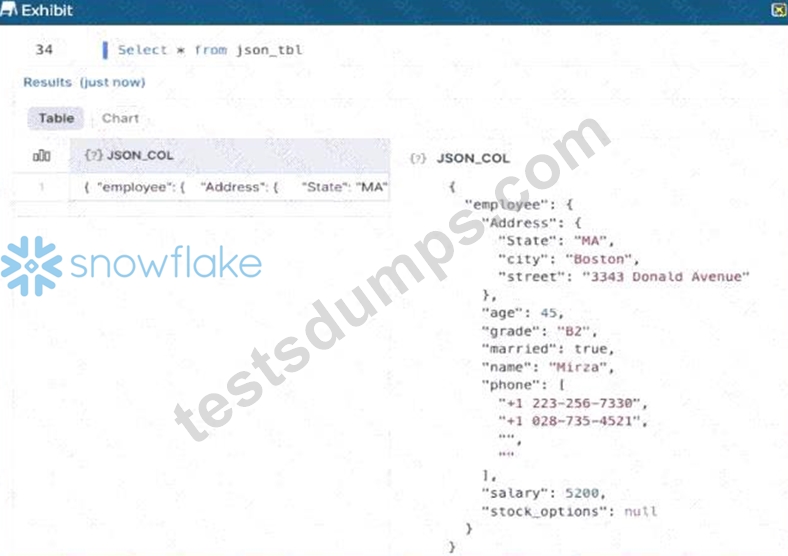
This SQL query is run: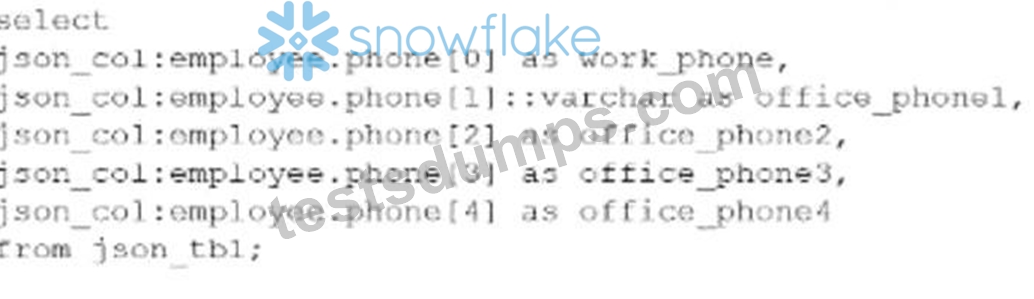
What will be the result?
- A.
- B.

- C.
- D.

Answer: D
Explanation:
To correctly predict the output of this query, a Data Analyst must understand how Snowflake handles semi- structured data (JSON), specifically regarding path notation, data type casting, and the display of VARIANT values in the Snowsight UI.
1. Variant vs. Casted Types (Display): When you access a value within a JSON object using colon notation (e.g., json_col:employee.phone[0]), the resulting value is of the VARIANT data type. In the Snowflake Snowsight results pane, VARIANT strings are displayed with double quotes (e.g., "+1 223-256-7330").
However, when you explicitly cast a variant to a string type using the double-colon syntax (e.g., ::varchar), Snowflake extracts the value as a native SQL string, which is displayed without quotes (e.g., +1 028-735-
4521).
2. Handling Empty Strings vs. Out-of-Bounds: In the provided JSON exhibit, the phone array contains four elements at indices 0, 1, 2, and 3. The elements at indices 2 and 3 are empty strings (""). When these are queried, Snowflake returns the empty string variant, which appears as "" in the result set. The query also attempts to access phone[4]. Since the array only has four elements (max index 3), index 4 is out-of-bounds.
In Snowflake, accessing a non-existent index in an array or a non-existent key in an object returns NULL.
Evaluating the Options based on the exhibit:
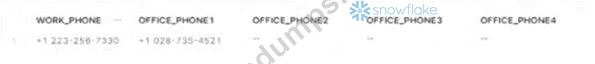
* Option B correctly reflects all these behaviors: WORK_PHONE is in quotes (Variant), OFFICE_PHONE1 is not in quotes (Casted), OFFICE_PHONE2 and OFFICE_PHONE3 show the empty strings present in the JSON, and OFFICE_PHONE4 correctly shows null for the out-of-bounds access.
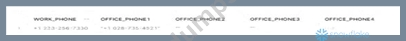
* Option A is incorrect because it misses the quotes for the variant column and shows the out-of-bounds index as an empty string instead of null.
* Option C is incorrect because it fails to account for the empty strings present at indices 2 and 3.
* Option D incorrectly mixes the casting logic and display.
This question tests the "Schema-on-Read" proficiency required of a SnowPro Advanced: Data Analyst, specifically the ability to predict exactly how transformed semi-structured data will materialize for end-users.
NEW QUESTION # 41
What functions should a Data Analyst use to run descriptive analytics on a data set? (Select TWO).
- A. ROW_NUMBER
- B. APPROX_COUNT_DISTINCT
- C. REGR_SLOPE
- D. AVG
- E. REGR_INTERCEPT
Answer: B,D
Explanation:
Descriptive analytics is the process of using historical data to understand "what happened." This typically involves summarizing large datasets into interpretable chunks using central tendency, dispersion, and frequency measures.
AVG (Average) is a cornerstone of descriptive statistics. It provides the arithmetic mean of a numeric column, allowing an analyst to understand the "typical" value within a dataset (e.g., Average Order Value).
APPROX_COUNT_DISTINCT is a descriptive tool used to understand the volume of unique entities within a dataset (e.g., "How many unique customers visited the site?"). Similar to HLL mentioned earlier, this function provides a fast summary of data volume and variety, which is a primary goal of the descriptive phase of analysis.
Evaluating the Options:
* Options A and B (REGR_INTERCEPT and REGR_SLOPE) are used for linear regression. These fall under Predictive Analytics, as they are used to model relationships and predict future outcomes, rather than just describing current data.
* Option C (ROW_NUMBER) is a window function used for data ranking and ordering, but it does not provide a descriptive summary of the dataset's characteristics.
* Options D and E are correct because they provide summary statistics (mean and cardinality) that define the "state" of the data, which is the definition of descriptive analytics.
NEW QUESTION # 42
You have a Snowflake table named 'CUSTOMER DATA' with a VARIANT column called 'PROFILE. This 'PROFILE column contains nested JSON objects with customer attributes. You need to extract the customer's first name from the 'PROFILE and handle cases where the 'firstName' field might be missing (NULL). Which of the following methods is the most efficient and concise way to achieve this?
- A.

- B.

- C.

- D.

- E.

Answer: B
Explanation:
Option E is the most efficient and concise. 'PROFILE:firstName' directly accesses the field, casts it to a string and 'IFNI-ILL' handles the potential NULL values, replacing them with 'Unknown'. Options A and C might return NULL if the field is missing. Option B is less efficient than direct path access. While option D works, casting to string is essential to ensure the correct datatype and to avoid any unexpected behaviors, making option E the ideal answer.
NEW QUESTION # 43
What option would allow a Data Analyst to efficiently estimate cardinality on a data set that contains trillions of rows?
- A. Count(Distinct *)/Count(*)
- B. SYSTEM$ESTIMATE
- C. HLL(*)
- D. Count(Distinct *)
Answer: C
Explanation:
When working with "Big Data" at the scale of trillions of rows, calculating an exact count of unique values using COUNT(DISTINCT column) is extremely resource-intensive. This is because Snowflake must keep track of every unique value encountered to ensure no duplicates are counted, leading to high memory usage and long execution times (often referred to as "spilling to disk").
To solve this, Snowflake provides HyperLogLog (HLL) functions. HLL(*) (or specifically HLL_ACCUMULATE and HLL_ESTIMATE) allows an analyst to estimate the cardinality (the number of unique elements) with a very small, known margin of error (typically around 1%). This is significantly faster and uses far fewer credits than an exact count because it uses a probabilistic algorithm rather than a state- heavy tracking mechanism.
Evaluating the Options:
* Option A is technically correct for small datasets but is highly inefficient for trillions of rows, directly contradicting the "efficiently" requirement of the question.
* Option C is a distractor; while Snowflake has various SYSTEM$ functions, SYSTEM$ESTIMATE is not a standard function for cardinality.
* Option D is a formula that doesn't target cardinality but rather a ratio (density).
* Option B is the correct answer. The HLL family of functions is the industry standard within Snowflake for high-performance cardinality estimation on massive datasets.
NEW QUESTION # 44
You have a Snowflake table named 'LOG DATA' with a "VARIANT' column called 'log_message" storing application logs in JSON format. The 'log_message' structure contains a nested JSON object called 'context' , which may or may not be present in every log entry. The 'context' object itself contains several key-value pairs, including potentially a 'user_id', a 'session_id' , and/or a 'request_id' You need to extract all the unique combination of 'user _ id' , and 'request_id' that exist across the dataset, accounting for instances where the 'context' object or any of the individual IDs are missing (represented as NULL). The goal is to ensure no errors are thrown due to missing fields. Select all the options which would achieve this outcome.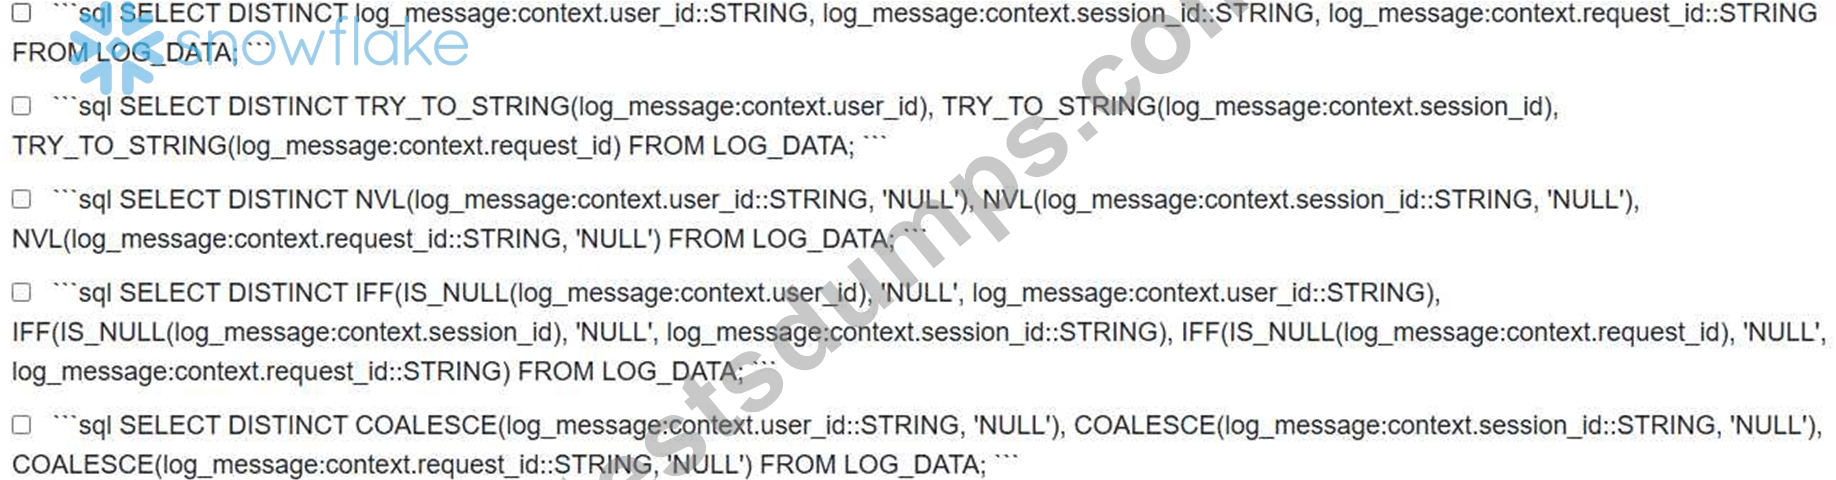
- A. Option E
- B. Option D
- C. Option C
- D. Option A
- E. Option B
Answer: A,E
Explanation:
Options B and E are both valid solutions. Option B Uses 'TRY TO_STRING' function. If value is not present and is NULL, then automatically it will be converted to Null without any failure. Option E Uses 'COALESCE will handle any missing 'context object or missing IDs within the 'context' object without throwing an error. If any of the three values are NULL then it would be converted to string 'NULL'. Why other options are not entirely correct Option A This is not a correct answer, as a result in case NULL values encountered, this will result in failures. Option C & D This is a valid solution, however, since NVL and IFF functions are slower compared to TRY _ TO STRING and COALESCE, this result in slow processing. So, its not entirely correct answer.
NEW QUESTION # 45
You are tasked with enriching a 'SALES DATA' table in Snowflake with geographic information based on IP addresses. You have access to an external function 'GEO LOOKUP(ip_address)' that returns a JSON object containing geographical details (city, region, country) for a given IP address. The 'SALES DATA' table contains 'SALE D', 'CUSTOMER D', ADDRESS', and 'SALE AMOUNT columns. You need to enrich the table with city and country information derived from the IP address. Which of the following statements will correctly add 'CITY' and 'COUNTRY columns to a new table 'ENRICHED SALES DATA based on the external function 'GEO LOOKUP , correctly handling potential NULL values and ensuring data type consistency?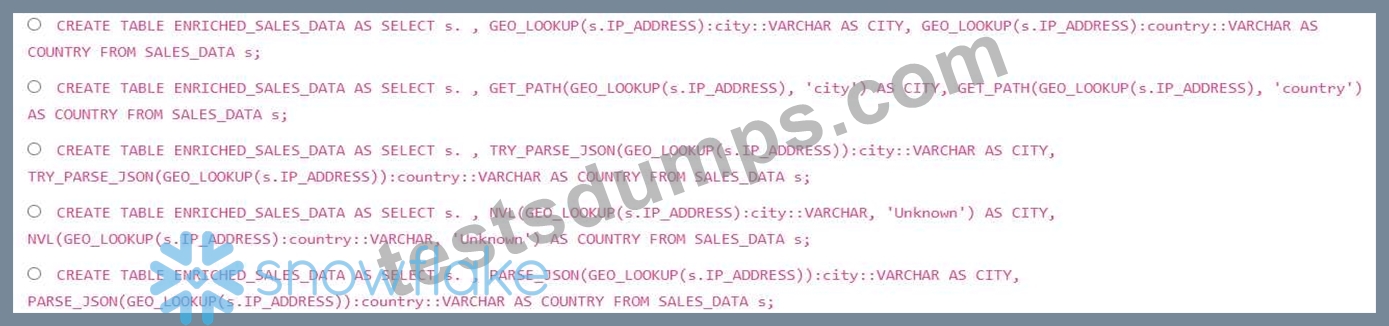
- A. Option E
- B. Option D
- C. Option C
- D. Option B
- E. Option A
Answer: B
Explanation:
Option D is the most robust solution. It extracts the city and country values from the JSON object returned by the function using the operator. The cast ensures the data is stored as strings. Critically, it uses to handle cases where the 'GEO_LOOKUP' function might return NULL (e.g., for invalid IP addresses), preventing errors and providing a default value ('Unknown'). Option A does not handle NULL, Option B's 'GET_PATH' is not a standard Snowflake function for JSON parsing, Options C parses the GEO LOOKUP output to json format if its not which can result in the 'CITY' and 'COUNTRY becoming 'NULL'. The option E 'PARSE_JSON' would throw errors on invalid json strings in the ip address.
NEW QUESTION # 46
Which statistical method is commonly used in forecasting based on historical data?
- A. Simple data aggregation
- B. Regression analysis
- C. Inferential statistics
- D. Data normalization
Answer: B
Explanation:
Regression analysis is frequently employed for forecasting based on historical data, predicting future trends based on past patterns.
NEW QUESTION # 47
You are tasked with building a dashboard in Looker Studio to visualize data from a Snowflake database. The data contains sensitive information, and the security team requires that only authorized users can access specific data based on their role. The Snowflake database has roles defined: 'ANALYST, 'MANAGER, and 'EXECUTIVE. The 'SALES DATA' table contains a 'REGION' column. 'ANALYST' should only see data for their assigned region, 'MANAGER should see data for their region and direct reports regions, and 'EXECUTIVE should see all regions. Which of the following is/are the MOST secure and efficient way(s) to implement row-level security in Snowflake and integrate it with Looker Studio without duplicating the data?
- A. Implement a Snowflake stored procedure that accepts a user's role as input and returns the filtered data. Connect Looker Studio to this stored procedure.
- B. Create dynamic data masking policies in Snowflake to redact sensitive 'SALE_AMOUNT data based on roles and connect Looker Studio using a service account.
- C. Implement Row Access Policies in Snowflake based on the USER NAME() or CURRENT ROLE() functions to filter the 'SALES DATA' table directly. Grant appropriate roles to users and connect Looker Studio using a service account that has the necessary privileges.
- D. Import the 'SALES DATA' table into Looker Studio and implement data blending with a user role mapping table to filter the data within Looker Studio.
- E. Create separate Snowflake views for each role, filtering the data based on the 'REGION' column. Connect Looker Studio to the appropriate view based on the user's role.
Answer: B,C
Explanation:
Row Access Policies (RAP) in Snowflake provide the most secure and efficient way to implement row-level security. By defining policies based on the user's role, you can ensure that users only see the data they are authorized to access directly at the Snowflake level. Combining RAPs with dynamic data masking for 'SALE_AMOUNT adds an extra layer of security by redacting sensitive data based on the user's role. Option A requires managing multiple views, which can be cumbersome. Option B introduces complexity with stored procedures. Option D moves security logic into Looker Studio, which is less secure and can be bypassed. Using a service account with appropriate privileges ensures that Looker Studio can access the data securely and apply the defined Row Access Policies. Options C is correct because it keeps security logic within Snowflake. Option E is correct because it provides additional data masking depending on the security policies for sale amount.
NEW QUESTION # 48
How do row access policies and Dynamic Data Masking impact the creation of dashboards concerning data visibility and security?
- A. Both policies restrict data visibility for better security.
- B. Dynamic Data Masking doesn't influence dashboard creation.
- C. They enhance data visibility for all users without limitations.
- D. Row access policies limit data visibility based on user privileges.
Answer: D
Explanation:
Row access policies limit data visibility based on user privileges, ensuring better security in dashboard creation.
NEW QUESTION # 49
A company ingests sensor data into a Snowflake table named READINGS with columns (VARCHAR), 'reading_time' (TIMESTAMP NTZ), and 'raw_value' (VARCHAR). The 'raw_value' column contains numeric data represented as strings, but sometimes includes non-numeric characters (e.g., '123.45', 'N/A', '500'). You need to calculate the average of the numeric raw_value' readings for each within the last hour, excluding invalid readings. Which of the following Snowflake SQL statements will correctly accomplish this, handling potential conversion errors and filtering for valid data?
- A. SELECT sensor_id, 'N/A'))) FROM SENSOR_READINGS WHERE reading_time DATEADD(hour, -1 , CURRENT TIMESTAMP()) GROUP BY sensor_id;
- B. SELECT sensor_id, FROM SENSOR_READINGS WHERE reading_time DATEADD(hour, -1, CURRENT _ TIMESTAMP()) GROUP BY sensor id;
- C. SELECT sensor_id, raw_value, NULL))) FROM SENSOR_READINGS WHERE reading_time DATEADD(hour, -1, CURRENT TIMESTAMP()) GROUP BY sensor_id;
- D. SELECT sensor_id, FROM SENSOR_READINGS WHERE reading_time DATEADD(hour, -1 , AND TRY_TO IS NOT NULL GROUP BY sensor_id;
- E. SELECT sensor_id, AVG(CASE WHEN THEN ELSE NULL END) FROM SENSOR_READINGS WHERE reading_time DATEADD(hour, -1, CURRENT TIMESTAMP()) GROUP BY sensor_id;
Answer: D
Explanation:
Option B is the correct answer because 'TRY TO NUMBER attempts to convert the 'raw_value' to a number, returning NULL if the conversion fails. The 'AND TRY_TO_NUMBER(raw_value) IS NOT NULL' clause then filters out these NULL values, ensuring only valid numeric readings are included in the average calculation. Option A will throw an error if it encounters a non-numeric value. Option C, while functionally correct, utilizes which can be less reliable for specific locale formats compared to Option D is unnecessarily complex and less readable. Option E only handles 'N/A', not other potential invalid values.
NEW QUESTION # 50
When working with semi-structured data in Snowflake, how do built-in functions for traversing, flattening, and nesting aid in data manipulation?
- A. They restrict data access for user roles
- B. They limit data transformation possibilities
- C. They facilitate handling complex and nested data structures
- D. They only work with specific file formats
Answer: C
Explanation:
Built-in functions for semi-structured data in Snowflake simplify handling complex and nested structures, making data manipulation more manageable and enhancing flexibility in data transformation.
NEW QUESTION # 51
How do materialized views differ from secure views in data analysis?
- A. Materialized views restrict data access for improved security.
- B. Materialized views offer enhanced data security while allowing selective data access.
- C. Secure views precompute data, unlike materialized views.
- D. Secure views provide precomputed snapshots, unlike materialized views.
Answer: C
Explanation:
Secure views offer enhanced data security without precomputing data, distinguishing them from materialized views.
NEW QUESTION # 52
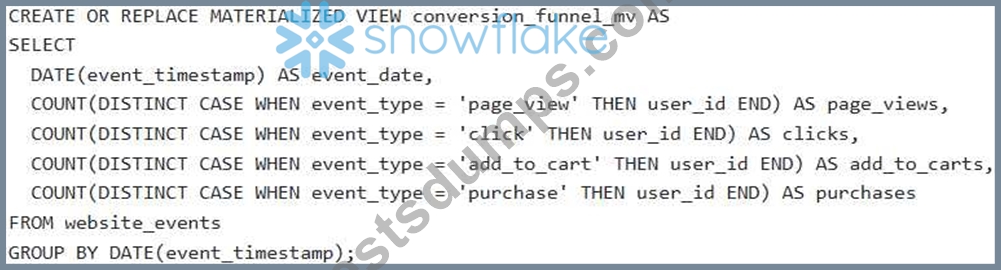
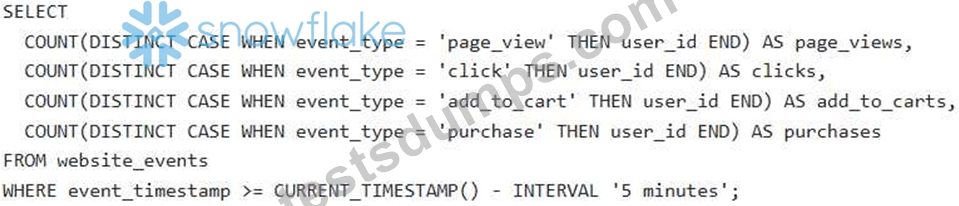
You are building a real-time dashboard to monitor website traffic and user behavior for an e-commerce company. The data includes page views, clicks, add-to-carts, and purchases, streamed continuously into Snowflake. You need to visualize the conversion funnel (page views -> clicks -> add-to-carts -> purchases) in real-time and identify drop-off points. Given the following table schema: "'sql CREATE OR REPLACE TABLE website_events ( event_timestamp TIMESTAMP NTZ, event_type VARCHAR(50), user_id VARCHAR(IOO), page_url VARCHAR(255) ); Which approach, including code snippets, would be the MOST efficient and scalable way to achieve this real-time conversion funnel visualization, taking into account the high volume of streaming data?
- A. Create a Snowflake Stream on the 'website_events' table. Create a Snowpipe to ingest data, and build a materialized view that pre-calculates the conversion funnel metrics. Connect a real-time dashboarding tool (e.g., Apache Superset, Grafana) to the materialized view to display the funnel in real-time.
- B. Export the 'website_events' data to a message queue (e.g., Kafka) and use a stream processing framework (e.g., Flink) to calculate conversion funnel metrics. Then, load the results into a separate table in Snowflake and visualize it using a BI tool.
- C. Periodically query the 'website_events' table every 5 minutes, calculate conversion rates for each stage of the funnel using SQL aggregate functions, and update a static chart in a reporting tool.
- D. Load all 'website_eventS table data into Python Pandas dataframes and use libraries to find the conversion rate in real time.
- E. Create a Snowflake Stream on the 'website_events' table. Develop a Snowpipe to continuously ingest data into the table. Utilize a BI tool like Tableau connected directly to the 'website_events' table. Build several dashboards each for event type.
Answer: A
Explanation:
Option C is the most efficient and scalable. A Snowflake Stream allows you to track changes to the 'website_events' table in real- time. A Snowpipe enables continuous data ingestion. A materialized view pre-calculates the conversion funnel metrics, significantly improving query performance compared to querying the base table directly, especially with high data volumes. Connecting a real-time dashboarding tool to the materialized view provides a real-time view of the funnel. Option A involves periodic querying, which is less real-time and less efficient. Option B suggests direct connection with a BI tool without pre-aggregating the Data, resulting into dashboard performance issue. Option D introduces unnecessary complexity with external message queues and stream processing frameworks. Exporting data to Python dataframe is not scalable for large data volumes.
NEW QUESTION # 53
A data analyst accidentally dropped a crucial table, 'SALES DATA', containing historical sales information. The table was dropped 5 days ago. The data retention period for the Snowflake account is set to the default value. The analyst needs to recover the table with all its data'. What is the MOST efficient and reliable method to recover the 'SALES DATA" table in Snowflake?
- A. create a clone of the table using Time Travel at a point in time before it was dropped, using the 'CREATE TABLE CLONE SALES DATA BEFORE(STATEMENT y command.
- B. Use the 'TIME TRAVEL' function in a SELECT statement to retrieve the data and recreate the table.
- C. Request Snowflake Support to restore the table from their backups.
- D. create a clone of the table using Time Travel at a point in time before it was dropped, using the 'CREATE TABLE CLONE SALES DATAAT (OFFSET -86400 5)' command.
- E. Restore the table using the 'UNDROP TABLE SALES DATA' command.
Answer: E
Explanation:
The 'UNDROP TABLE command is the most efficient and direct method to recover a dropped table, as long as it's within the data retention period. Since the table was dropped 5 days ago and the default retention period is typically sufficient (can be up to 90 days in Enterprise Edition), 'UNDROP TABLE should work. While options B and E are valid uses of cloning and time travel, they involve creating a new table and are less direct. Requesting Snowflake support (C) is unnecessary for a simple table recovery. Option D will require data extraction and recreating the table structure, which is tedious and time-consuming compared to 'UNDROP'
NEW QUESTION # 54
You are building a sales performance dashboard in Snowflake. You need to incorporate a custom metric called 'Sales Efficiency', which is calculated as (Total Sales Revenue / Number of Sales Representatives) 1000. You want to expose this metric in your dashboard and allow users to filter data based on specific Sales Efficiency ranges. You also want to allow filtering by region and quarter. Which of the following approaches would be MOST performant and maintainable in Snowflake?
- A. Create a Snowflake user-defined function (IJDF) in JavaScript to calculate 'Sales Efficiency'. Use this IJDF in the dashboard queries, along with standard WHERE clauses for region and quarter filtering.
- B. Calculate 'Sales Efficiency' directly in the dashboard tool for each query using its expression engine. Implement region and quarter filtering within the dashboard tool.
- C. Create a Snowflake stored procedure that calculates 'Sales Efficiency' based on the selected Region and Quarter. The dashboard calls the stored procedure and displays the returned result set.
- D. Create a Snowflake view that calculates 'Sales Efficiency'. The dashboard queries filter this view using standard WHERE clauses for region and quarter. No indexes or partition keys are created.
- E. Create a materialized view in Snowflake that pre-calculates 'Sales Efficiency', region, and quarter. Include appropriate indexes and partition keys on the view. Expose the materialized view to the dashboard.
Answer: E
Explanation:
A materialized view (option C) is the most performant option. It pre-calculates the 'Sales Efficiency' metric and stores the results, allowing for fast retrieval. Proper indexing and partitioning further optimize query performance. Performing the calculation in the dashboard tool (option A) is inefficient for large datasets. IJDFs (option B) can be slower than native SQL. A regular view (option D) does not store the pre- calculated data, so the calculation is performed every time the view is queried. Stored procedures are typically less efficient for dashboard queries than materialized views, as they need to be executed each time.
NEW QUESTION # 55
You are developing a Snowflake stored procedure that uses an external Python library (e.g., scikit-learn for machine learning). The library is not natively available within Snowflake's Python environment. What is the correct process to include and utilize this external library within your stored procedure?
- A. Create a Snowflake stage, upload the library's '.whl' file to the stage, and then use the 'CREATE PROCEDURE statement with the 'IMPORTS' clause to specify the stage and .whl' file. Snowflake will then install the library during procedure creation.
- B. Upload the library using the Snowflake web interface, so Snowflake will know which library it should be using.
- C. Simply import the library in your Python code within the stored procedure. Snowflake automatically downloads and installs any missing libraries from PyPl when the procedure is executed.
- D. Use the 'pip install' command within the stored procedure's Python code to install the library from PyPl during each execution of the procedure.
- E. Include the source code of the library directly within the stored procedure's Python code.
Answer: A
Explanation:
Option B is the correct approach. Snowflake uses stages and the 'IMPORTS' clause to manage external dependencies for Python stored procedures. You must upload the .whl' file of the library to a stage and then reference it in the 'CREATE PROCEDURE' statement. This ensures that the library is available when the procedure is executed. Option A is incorrect because Snowflake does not automatically download libraries from PyPl. Option C is incorrect because you cannot execute shell commands like 'pip install' within a stored procedure. Option D is generally impractical for larger libraries, and Option E isn't a valid approach.
NEW QUESTION # 56
......
Authentic Best resources for DAA-C01 Online Practice Exam: https://www.testsdumps.com/DAA-C01_real-exam-dumps.html
Updates Up to 365 days On Developing DAA-C01 Braindumps: https://drive.google.com/open?id=1ezNwskLyBZNKOQDynxApGwBaeCRL0zpo
